Hire senior AI / ML engineers
Vetted AI and ML engineers ready to work on your team this week — spanning LLM app development, agent design, RAG systems, fine-tuning, and MLOps.
What our AI / ML engineers bring to your team
Every engineer we place has shipped AI systems to real users — not tutorials, not demos, production code with SLOs.
LLM app development
End-to-end LLM apps — prompt design, model routing, streaming interfaces, structured outputs, and safety layers.
Agent & RAG systems
Multi-step agents, tool use, retrieval pipelines, and evaluation harnesses built with LangGraph and LlamaIndex.
Model fine-tuning
LoRA, QLoRA, and full-parameter fine-tuning with dataset curation, eval design, and reproducible training runs.
MLOps & serving
Model registries, inference endpoints, GPU autoscaling, and cost/latency monitoring for production ML systems.
Evaluation frameworks
Golden sets, LLM-as-judge scoring, regression suites, and CI gates that make quality a number you can move.
Enterprise integrations
Wire AI features into your existing product — SSO, tenant isolation, audit logs, and your data warehouse.
The AI / ML stack they work in
Every engineer we place is comfortable across at least six of these — deployed to production, not read about.
The work our AI engineers ship in production
The types of systems our engineers have delivered against real user traffic and enterprise data.
Enterprise copilots
Product- or domain-specific copilots grounded in your data, integrated with SSO and role-based access.
Multi-step AI agents
Tool-using agents that plan, act, and self-correct across workflows like triage, research, and back-office automation.
Grounded RAG systems
Retrieval pipelines with chunking strategy, hybrid search, reranking, and citation-first answer generation.
Fine-tuned domain models
Smaller, cheaper models tuned to your task — with an eval harness that proves they beat the general-purpose baseline.
MLOps platforms
Training-to-serving pipelines with dataset versioning, experiment tracking, and rollout controls.
AI product features
Smart search, summarization, drafting, and classification embedded into an existing SaaS product.
From requirements call to first commit
A tight four-step flow — no shopping résumés, no agency friction, engineers on your team within a week.
Requirements call
A 45-minute call with our engineering lead to scope skills, seniority, tooling, and the specific problems the hire will own.
Shortlist in 48 hours
Two or three matched engineer profiles delivered within 48 hours, each with recent AI project work you can review.
Technical interviews
Interview shortlisted engineers directly — no gatekeeping. Use your own rubric or borrow one of ours.
Start within a week
Selected engineer joins your Slack, repos, and standups. Contract, invoicing, and onboarding handled by us.
What you get that in-house hiring misses
Building an AI team from scratch takes quarters. Ours starts moving your roadmap this week.
Senior-only engineers
Every engineer we place has shipped production AI systems. No juniors billed as seniors, no résumé inflation.
Start in 48 hours
Shortlists back within two business days. First engineer on the team within a week — not a hiring quarter.
No agency markup layers
You work directly with our engineering lead and the engineers themselves. No account manager between you and the work.
Own your codebase from day one
All code, prompts, evals, and infra live in your repos and your cloud. No lock-in, no proprietary tooling.
A system built by the engineers we place
A grounded, tool-using assistant delivered by the same bench you would be hiring from.
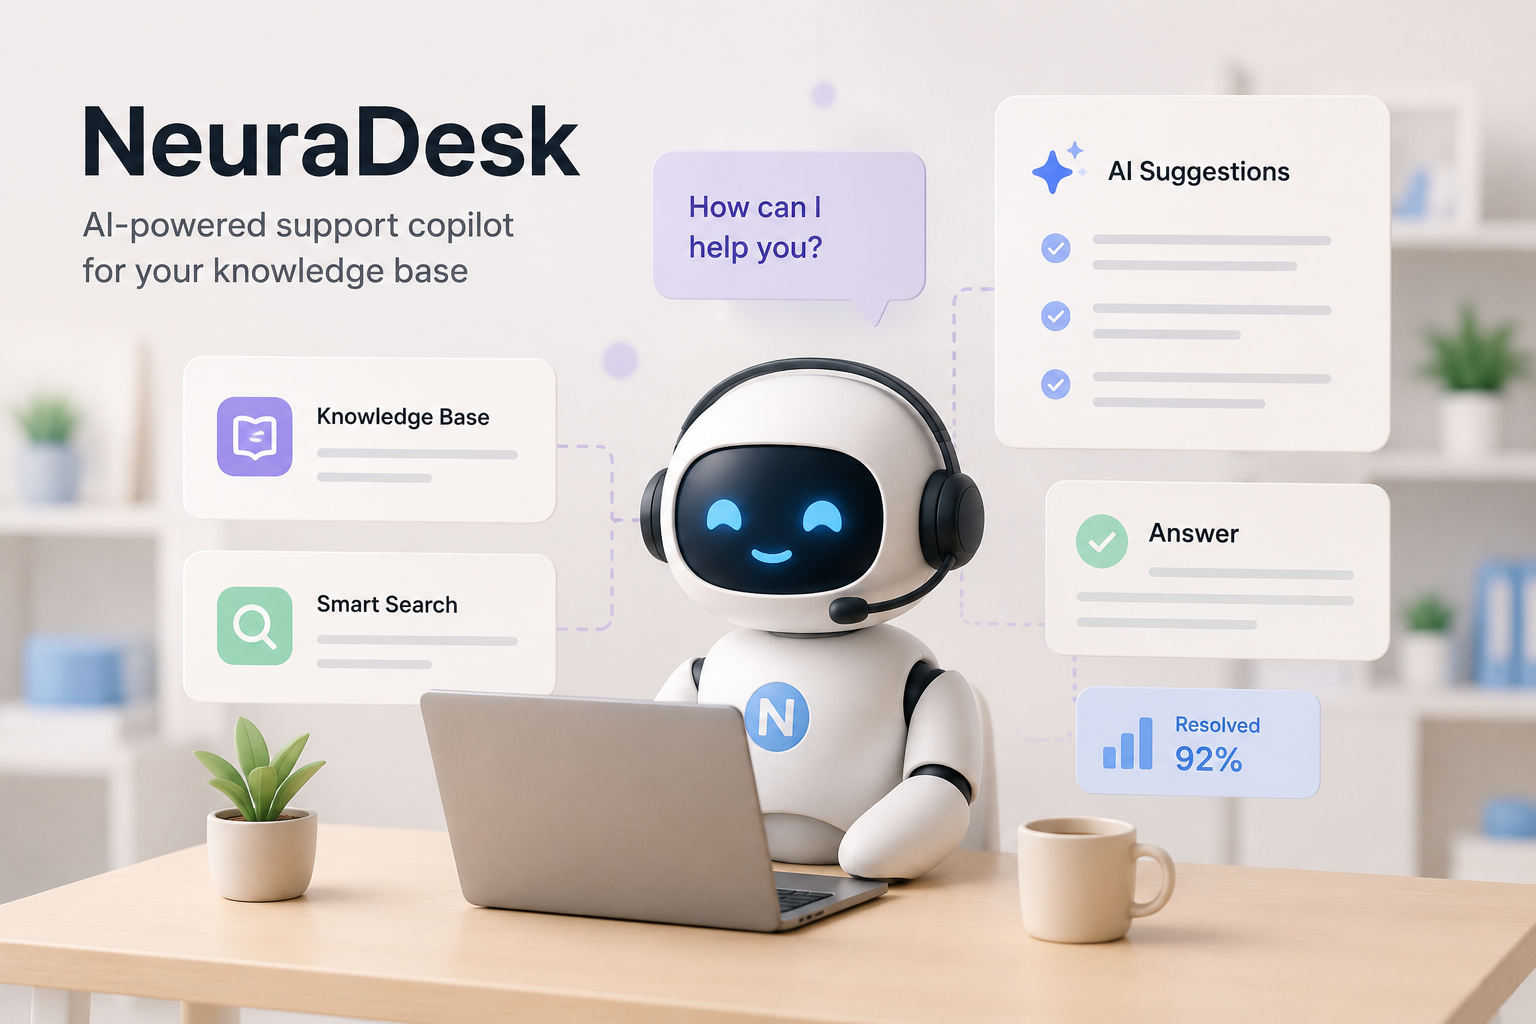 AI • RAG
NeuraDesk
A retrieval-augmented support copilot that grounds answers in a company's own knowledge base.
Read Case Study →Why teams hire AI engineers through us
A senior bench, direct engagement, and a delivery record that other AI hiring channels don't match.
Learn more about us →Real production AI experience
Our engineers have shipped RAG, agents, and fine-tuned models against real users — not built notebooks and left.
Direct access to the engineers
You interview, choose, and work with the engineers themselves. No layers of account management or handoffs.
Vetted for evals, not just prompts
Prompt-crafting is table stakes. Our engineers are vetted for evaluation design, cost control, and safety.
You keep the codebase and the keys
Code in your repos, keys in your vaults, models swappable. No dependence on our platform to keep running.
Common questions about hiring AI engineers
Practical answers on seniority, engagement, timelines, and how our engineers plug into your team.
How do you vet AI / ML engineers?
What seniority levels can you place?
Can I hire for a short-term project?
Do your engineers work in my time zone?
Who owns the code and IP?
Can engineers work through my staffing vendor or MSA?
Need an AI engineer on your team this week?
Tell us the problem and the stack. We'll come back with a shortlist within 48 hours.
Book a Consultation →